AI Token Economics
Token counts make AI consumption easy to measure, but they reveal only a fraction of what an AI workload actually costs. Understanding AI economics requires looking beyond model tokens to infrastructure, tools, workflows, failures, human intervention, and ultimately the business outcome produced.
Tokens are the cheapest thing to measure and the least useful
Last reviewed: September 2026
Tokens are one of the easiest costs to measure in generative AI, but token spend alone says very little about whether an AI system is economically effective. This guide follows the full cost of an AI task, from model consumption and infrastructure to retries, tools, human escalation, and the final business outcome. It also explains how to move from AI cost monitoring toward meaningful unit economics.
In one sentence: AI token economics connects model consumption with the full cost and business value of delivering an AI-powered outcome.
What is AI token cost?
AI token cost is the amount charged for the input and output tokens processed by a language model. It is one component of AI cost, but it should not be confused with the total cost of operating an AI application, agent, or workflow.
Large language models process text in units called tokens.
Commercial model APIs commonly price usage according to the number of input and output tokens processed.
At its simplest:
Model cost = input token cost + output token cost
Suppose a workload processes:
10 million input tokens at €2 per million
2 million output tokens at €8 per million
Input cost:
10 × €2 = €20
Output cost:
2 × €8 = €16
Total model cost:
€20 + €16 = €36
This calculation is useful.
It tells you what the model invocation cost.
It does not tell you what the task cost.
Why tokens are easy to measure
Tokens have several characteristics that make them attractive as a cost metric.
They are quantifiable.
They can usually be attributed to a model request.
Providers often expose them directly.
They have an identifiable price.
That makes token dashboards relatively straightforward to build.
You can measure:
input tokens
output tokens
cached tokens
model
provider
request
application
user
agent
All of this can be valuable.
The problem begins when token cost is treated as a proxy for the economics of the complete AI service.
A token is a consumption unit, not a business outcome
Imagine two AI agents.
Agent A
Model cost per task: €0.04
Success rate: 60%
Agent B
Model cost per task: €0.09
Success rate: 95%
Looking only at token/model cost makes Agent A appear cheaper.
Now run each agent across 10,000 tasks.
Agent A:
10,000 × €0.04 = €400
Agent B:
10,000 × €0.09 = €900
Agent B costs more than twice as much at the model layer.
But now consider outcomes.
Agent A successfully completes:
10,000 × 60% = 6,000 tasks
Model cost per successful outcome:
€400 ÷ 6,000 = €0.067
Agent B successfully completes:
10,000 × 95% = 9,500 tasks
Model cost per successful outcome:
€900 ÷ 9,500 = €0.095
The gap has already narrowed.
And we still haven't included the cost of failure.
The full cost stack of an AI task
An AI-powered task can involve substantially more than an LLM invocation.
A more complete cost model may include:
1. Model consumption
Input tokens, output tokens, embeddings, multimodal processing, cached context, and other provider charges.
2. Compute infrastructure
GPU or CPU resources used for self-hosted models, inference, orchestration, preprocessing, or supporting services.
3. Data and storage
Vector databases, object storage, retrieval systems, databases, data pipelines, and data transfer.
4. Tools and APIs
Search services, external APIs, SaaS tools, code execution, document processing, or other services called by an agent.
5. Orchestration and observability
Agent platforms, gateways, tracing, monitoring, logging, evaluation, security, and other supporting infrastructure.
6. Retries and failed attempts
A workflow may invoke a model several times before producing a usable result.
Those attempts still cost money.
7. Human escalation
When the AI system cannot complete the task, a person may need to review, correct, approve, or complete it.
This can easily change the economics of the workflow.
The complete question is therefore not:
How much did the tokens cost?
It is:
How much did it cost to produce the outcome?
Worked example: the cost of 10,000 AI support tasks
Consider an AI customer-support workflow processing 10,000 cases per month.
Its monthly costs are:
Cost component | Monthly cost |
|---|---|
Model/API consumption | €600 |
AI infrastructure & orchestration | €450 |
Data, storage & retrieval | €200 |
External tools/APIs | €150 |
Observability & monitoring | €100 |
AI system subtotal | €1,500 |
If we stop here:
€1,500 ÷ 10,000 = €0.15 per attempted case
That looks inexpensive.
But the AI system resolves only 8,500 cases successfully without human intervention.
The remaining 1,500 cases are escalated to humans.
Suppose each escalation requires an average of 8 minutes of human work and the fully loaded labor cost is €36 per hour.
Human time required:
1,500 × 8 minutes = 12,000 minutes
12,000 ÷ 60 = 200 hours
Human escalation cost:
200 × €36 = €7,200
Now the full monthly cost is:
€1,500 + €7,200 = €8,700
Human escalation represents:
€7,200 ÷ €8,700 = 82.8% of total cost
The AI infrastructure itself represents only 17.2%.
This is why a token-cost dashboard can be perfectly accurate while providing a very incomplete picture of AI economics.
Cost per attempt vs cost per successful outcome
Using the same example, there are several ways to describe unit cost.
Total cost per attempted case:
€8,700 ÷ 10,000 = €0.87
But suppose 300 of the escalated cases ultimately fail to reach the required outcome.
Successful outcomes:
10,000 − 300 = 9,700
Cost per successful outcome:
€8,700 ÷ 9,700 = €0.897
Approximately:
€0.90 per successful outcome
Now compare that with the model/API spend alone:
€600 ÷ 10,000 = €0.06 per attempt
Both €0.06 and €0.90 are mathematically valid.
But they describe radically different things.
€0.06 describes model consumption per attempted task.
€0.90 describes the approximate full cost per successful business outcome.
Before comparing AI unit costs, always ask:
Cost per what?
Human escalation can dominate AI economics
Human escalation deserves special attention because it is easy to omit.
AI infrastructure costs are machine-readable.
Labor costs often live somewhere else entirely.
That separation can produce misleading optimization decisions.
Return to our example.
Suppose a more capable model increases API expenditure from €600 to €1,100 per month but reduces escalations from 1,500 cases to 500.
At 8 minutes per escalation:
500 × 8 = 4,000 minutes
4,000 ÷ 60 = 66.7 hours
Human cost:
66.7 × €36 ≈ €2,401
Assume the other €900 of non-model system costs remain unchanged.
The new total becomes:
€1,100 + €900 + €2,401 = €4,401
The organization increased model spending by:
€500
Yet total workflow cost fell from:
€8,700 → €4,401
That is a reduction of approximately:
49.4%
Optimizing for the cheapest model would have produced the wrong economic decision.
The more expensive model is cheaper at the level that matters: the complete workflow.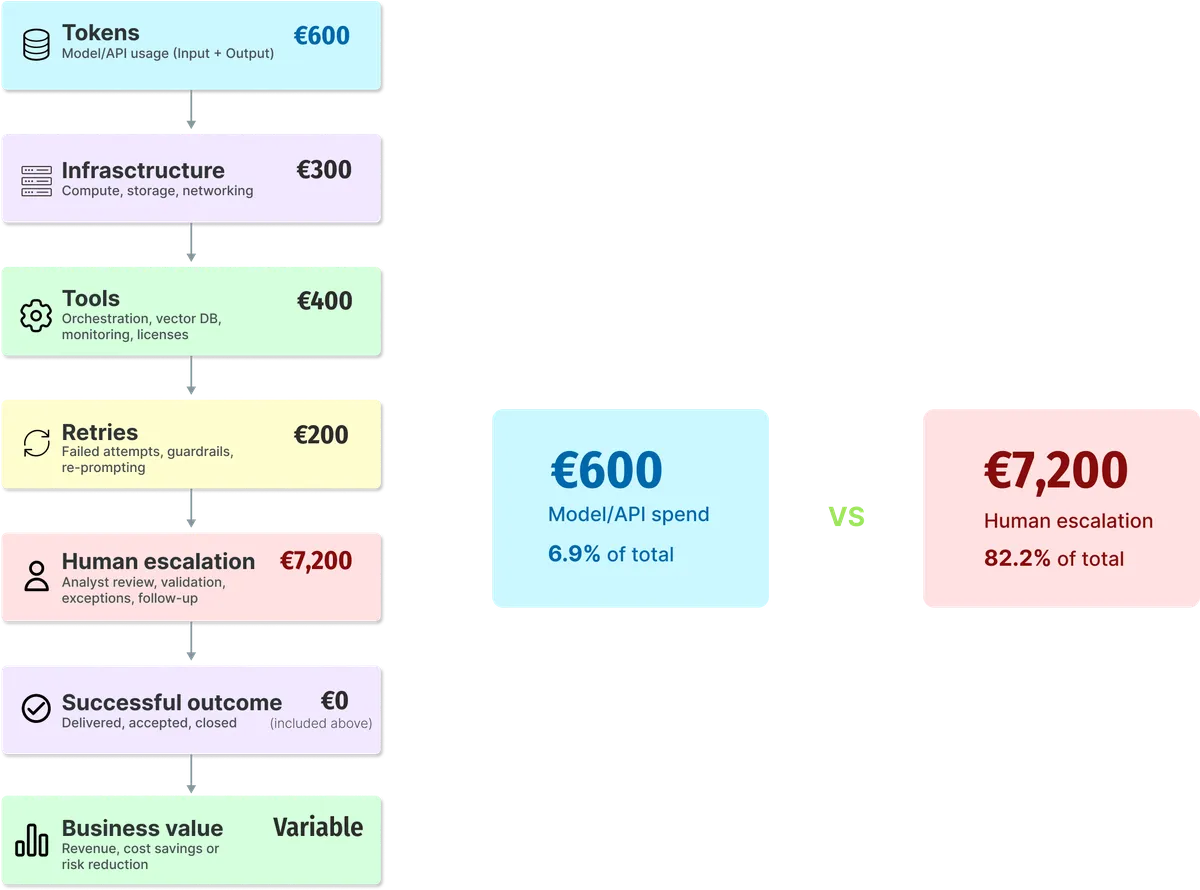
AI agents make attribution harder
Traditional application cost attribution often follows relatively predictable infrastructure relationships.
Agentic systems can be different.
A single user request might trigger:
an orchestration agent,
a retrieval operation,
another model,
an external API,
a specialist agent,
a retry,
a validation step,
and finally a human escalation.
Which agent caused the cost?
Which customer should receive it?
Which business process benefited?
And if several agents collaborated on the outcome, how should shared costs be allocated?
Token counts alone cannot answer those questions.
Agent cost management therefore requires both technical telemetry and business context.
Measuring AI cost at different levels
A useful AI cost model can operate at several layers.
Cost per token
Useful for model consumption and provider comparison.
Cost per request
Useful for API-level operational monitoring.
Cost per agent run
Useful for understanding autonomous workflows.
Cost per workflow
Useful when several models, agents, tools, or services collaborate.
Cost per customer
Useful for cost-to-serve and customer profitability.
Cost per successful outcome
Useful for evaluating whether the AI system delivers results efficiently.
Cost per unit of business value
Potentially the most meaningful level, although often the hardest to calculate.
Examples might include:
cost per resolved support case
cost per qualified lead
cost per completed order
cost per approved claim
cost per generated software feature
cost per successfully processed document
As you move down this list, measurement becomes harder.
It also becomes more economically meaningful.
The cheapest AI workflow is not necessarily the most efficient
Suppose Workflow A costs €0.30 per attempt and Workflow B costs €0.50.
A simple cost dashboard favors Workflow A.
But suppose:
Workflow A succeeds 60% of the time.
Workflow B succeeds 95% of the time.
Ignoring other costs:
Workflow A:
€0.30 ÷ 60% = €0.50 per successful outcome
Workflow B:
€0.50 ÷ 95% ≈ €0.53 per successful outcome
They're now almost equivalent.
Add different human escalation rates, customer value, latency, quality, or failure consequences and the comparison can reverse completely.
Cost optimization without outcome measurement can therefore optimize the wrong variable.
From AI cost management to AI unit economics
The progression can be thought of as:
Tokens → Requests → Agents → Workflows → Outcomes → Business value
Each layer answers a different question.
Tokens tell you what the model consumed.
Requests tell you what an application invoked.
Agents tell you which autonomous component performed work.
Workflows tell you what the complete process consumed.
Outcomes tell you what was successfully accomplished.
Business value tells you whether the outcome was worth producing.
This is where AI cost management begins to become AI unit economics.
Allocating shared AI costs
Not every AI cost maps neatly to a single request.
Organizations may operate shared:
GPU clusters
vector databases
observability platforms
model gateways
agent platforms
data pipelines
evaluation systems
engineering services
These costs need an allocation method.
A shared GPU cluster could be allocated by GPU-hours.
A vector database could use storage or query volume.
An observability platform might be allocated by traces or workload volume.
Some platform costs might use a fixed or proportional allocation.
Others may remain explicitly unallocated.
The important principle is the same as for other technology costs:
The allocation driver should have a defensible relationship with the cost being distributed.
See Cost allocation for a detailed comparison of allocation methods.
AI ROI requires a value side
Reducing cost is not the same as increasing ROI.
Suppose an AI workflow costs €50,000 per month.
Without knowing what it produces, we cannot say whether €50,000 is good or bad.
If it generates €20,000 of measurable value, the economics are problematic.
If it replaces or enables €300,000 of productive activity, the same €50,000 tells a very different story.
This is why mature AI financial management needs both sides of the equation:
What did the AI consume?
and
What did the AI produce?
The second question is usually harder.
It is also more important.
Data maturity: crawl, walk, run
Not every organization can measure cost per business outcome immediately.
That should not prevent it from starting.
Crawl
Start with the information already available:
provider bills
model usage
token counts
infrastructure costs
application or customer identifiers
The objective is basic visibility.
Walk
Add operational context:
agents
workflows
traces
tools
retries
ownership
human escalation
The objective becomes attribution.
Run
Connect technical consumption with business outcomes:
successful transactions
customer value
campaign results
revenue
productivity
quality
contribution margin
The objective becomes unit economics and ROI.
A company might obtain this information through mature observability systems such as OpenTelemetry, internal databases, commercial systems, provisioning platforms, or even relatively simple business datasets.
The important point is not where the data originates.
It is whether technical consumption can be correlated with the outcome the organization cares about.
How Exivity supports AI token economics
AI cost data rarely comes from one source.
Model consumption may come from an API provider. Self-hosted models may generate infrastructure telemetry. Agent activity may appear in OpenTelemetry traces. Business outcomes may live in CRM, support, commerce, marketing, or internal systems.
Exivity is designed to bring different consumption and business datasets together and apply a common cost model across them.
That can include AI token consumption, infrastructure costs, agents, services, customers, and other operational or business dimensions where the required data is available.
Instead of stopping at token expenditure, organizations can build reports around questions such as:
Which agent consumed what?
What does this workflow cost?
Which customer or service generated the consumption?
How much do failed attempts cost?
What is the cost per successful outcome?
How does AI expenditure relate to business activity?
The exact level of analysis depends on the organization's available data and maturity.
The objective is not to replace observability systems or business applications. It is to correlate their data so technology consumption can be understood in financial and business terms.
From token metering to financial accountability
Tokens remain useful.
They provide a granular, measurable unit of AI consumption and can be an important input into allocation and billing.
But they are the beginning of the cost model, not the end.
An AI system can reduce token consumption while increasing retries.
It can use a cheaper model while creating more human work.
It can reduce infrastructure cost while lowering successful outcomes.
Or it can deliberately increase model expenditure while reducing the total cost to serve a customer.
The economically relevant question is therefore rarely:
How many tokens did we use?
It is:
What did it cost us to produce a successful outcome, and what was that outcome worth?
Related: Unit economics · Cost allocation · Chargeback vs showback · FOCUS, explained
Frequently asked questions
The questions people ask about this once they start doing it, in the words they use.
Ask us about your use caseWhat is AI token cost?
AI token cost is the amount charged for tokens processed by an AI model. Providers may price input, output, cached, or other token types differently.
Why is token cost not the same as the cost of an AI task?
Tokens only price the model call. An AI task also consumes compute or GPU infrastructure, storage and data processing, external APIs and tools, observability and platform services, failed attempts and retries, and often human review or escalation. Counting tokens alone underestimates what it costs to deliver the service.
How do you calculate cost per successful outcome for an AI workflow?
Add up every cost layer for the workflow over a period, then divide by the number of tasks that were actually resolved rather than the number attempted. If 1,000 requests cost €1,000 in total and 850 are resolved successfully, the cost per successful outcome is €1.18, not the €1.00 cost per request.
Why does human escalation matter so much?
Human review and correction is frequently one of the largest cost lines in an AI workflow, and it is the one most often left out. A model that needs frequent manual intervention can cost more per successful outcome than a more expensive model that resolves more tasks on its own.
Is a cheaper model always cheaper?
Not per outcome. A cheaper model can lower token cost and still raise the cost per successful result if it triggers more retries, tool calls, and escalations. The comparison that matters is total cost per successful outcome, not price per token.
How should AI agent costs be allocated?
Agent costs can be attributed using telemetry such as model requests, traces, workflow identifiers, infrastructure consumption, customer information, or other usage data. Shared platform costs may require additional allocation rules.
What data do we need to measure AI economics properly?
Token usage per call, the infrastructure and GPU cost under it, tool and API charges, failed attempts and retries, human time spent on review or escalation, and a success signal for each task, all attributable to the same task or agent run so they can be rolled up to the outcome.
How do we connect AI cost to business value?
Pick the outcome the business recognises, such as a resolved support case, a qualified lead, a generated document, or a completed transaction, measure the full cost per outcome, and set it against the value that outcome produces. That is the step from AI cost to AI return on investment.
What is AI FinOps?
AI FinOps applies financial management practices to AI-related technology consumption, helping organizations understand ownership, cost, usage, efficiency, and business value across AI workloads.
How do you measure AI ROI?
AI ROI requires connecting the total cost of an AI workflow with measurable business value or outcomes. Depending on the use case, this might include revenue, completed transactions, resolved cases, productivity gains, avoided costs, or contribution margin.
Want the specifics on your own numbers?
A demo scoped to the problem this guide describes, run by an engineer. Bring one cost source; leave with a recommendation.