Cost Allocation
Cloud cost allocation is the process of assigning technology costs to the teams, products, customers, projects, or services responsible for them. A good allocation model makes shared technology spend easier to understand and creates a foundation for financial accountability, showback, chargeback, and FinOps.
Last reviewed: September 2026
Cloud cost allocation is the process of assigning technology costs to the teams, products, customers, projects, applications, or services responsible for them. This guide explains the most common allocation methods, how shared and untagged costs should be treated, and why the same cloud bill can produce very different results depending on the allocation method you choose.
In one sentence: Cost allocation determines who or what should be accountable for each portion of technology spend.
What is cloud cost allocation?
Cloud cost allocation is the process of assigning cloud and technology costs to the business entities responsible for consuming or benefiting from them.
Those entities might be departments, engineering teams, applications, products, customers, projects, environments, cost centers, or another organizational dimension.
Some costs are easy to allocate.
If a cloud resource belongs exclusively to Product A and costs €500, assigning the €500 to Product A is straightforward.
Other costs are much harder.
A Kubernetes cluster might support dozens of applications. A database might serve multiple products. A platform engineering team might operate infrastructure used across the entire organization. Network, security, monitoring, support, and reserved capacity can all create costs without one obvious owner.
Cost allocation is the process of deciding how those costs should be distributed.
The objective is not simply to make every cost disappear into a business unit. A useful allocation model should make technology spending more understandable and economically meaningful.
Why cloud cost allocation matters
A cloud bill tells you where money was spent.
Cost allocation tries to tell you who or what the money was spent for.
That distinction becomes increasingly important as technology environments become more complex.
Suppose an organization spends €1 million per month across AWS, Azure, Kubernetes, SaaS platforms, and private infrastructure.
Knowing that €400,000 went to compute and €150,000 to storage may help infrastructure teams.
But business questions usually look different:
How much does Product A cost to operate?
Which department owns this increase?
What does Customer X cost us to serve?
How much infrastructure does the development environment consume?
Which costs are shared?
How much spend currently has no reliable owner?
Allocation creates the bridge between technical consumption and those business questions.
Direct, shared and unallocated costs
Before choosing an allocation method, it helps to distinguish three broad types of cost.
Direct costs
A direct cost has a clear owner.
If a database exists exclusively for Product A and costs €3,000 per month, the €3,000 can normally be assigned directly to Product A.
These are usually the easiest costs to allocate.
Shared costs
A shared cost benefits or supports multiple consumers.
Examples include:
shared Kubernetes clusters
networking
observability platforms
security services
databases
support teams
shared storage
platform engineering
common SaaS subscriptions
These costs require a rule for determining how much each consumer should receive.
Unallocated costs
An unallocated cost is a cost that has not been assigned to a consumer.
That can happen because ownership information is missing, metadata is incomplete, the resource genuinely has no individual owner, or the organization deliberately chooses not to distribute a shared cost.
Unallocated does not necessarily mean incorrect.
Sometimes it is the most accurate description of what the organization currently knows.
Five ways to allocate the same cloud cost
There is no single allocation method that works for every cost.
To see why, consider one shared dataset and carry it through five different allocation methods.
A shared platform costs €12,000 per month and supports three products:
Product | Measured usage | Revenue | Users |
|---|---|---|---|
Product A | 600 units | €100,000 | 5,000 |
Product B | 300 units | €60,000 | 3,000 |
Product C | 100 units | €40,000 | 2,000 |
Total | 1,000 units | €200,000 | 10,000 |
The underlying cost never changes.
It is always €12,000.
Only the allocation method changes.
Method 1: Equal allocation
The simplest approach is to divide the cost equally.
There are three products:
€12,000 ÷ 3 = €4,000
Product | Allocated cost |
|---|---|
Product A | €4,000 |
Product B | €4,000 |
Product C | €4,000 |
Equal allocation is simple and predictable.
But Product C uses only 10% of the measured resources while receiving 33.3% of the cost.
That may be acceptable if the platform exists equally for all three products. It is less defensible if resource consumption is the primary driver of cost.
Method 2: Usage-based allocation
Now allocate according to measured usage.
Product A consumes 600 of 1,000 units, or 60%.
€12,000 × 60% = €7,200
Product B consumes 30%:
€12,000 × 30% = €3,600
Product C consumes 10%:
€12,000 × 10% = €1,200
Product | Usage share | Allocated cost |
|---|---|---|
Product A | 60% | €7,200 |
Product B | 30% | €3,600 |
Product C | 10% | €1,200 |
This model creates a strong connection between consumption and accountability.
It is particularly useful when the measured unit has a meaningful relationship with the cost being allocated.
But usage-based allocation is only as useful as the metric underneath it.
Allocating database costs according to API calls, for example, may be misleading if storage rather than requests is the primary cost driver.
Method 3: Revenue-based proportional allocation
The organization could instead treat the platform as a business-enabling cost and distribute it according to product revenue.
Product A generates 50% of revenue:
€12,000 × 50% = €6,000
Product B generates 30%:
€12,000 × 30% = €3,600
Product C generates 20%:
€12,000 × 20% = €2,400
Product | Revenue share | Allocated cost |
|---|---|---|
Product A | 50% | €6,000 |
Product B | 30% | €3,600 |
Product C | 20% | €2,400 |
The allocation is no longer based on technical consumption.
That is not inherently wrong.
It answers a different question: how should this shared platform cost be distributed relative to the economic scale of the products it supports?
Method 4: User-based allocation
Another option is to allocate according to active users.
Product A has 50% of users, Product B 30%, and Product C 20%.
The result is therefore:
Product | User share | Allocated cost |
|---|---|---|
Product A | 50% | €6,000 |
Product B | 30% | €3,600 |
Product C | 20% | €2,400 |
In this example, the result happens to match the revenue allocation.
But the underlying logic is completely different.
If user behavior or product pricing changes, the two models will diverge.
This illustrates an important principle:
An allocation number is meaningful only when you know what drove it.
Method 5: Fixed allocation
Finally, management might decide that the platform exists primarily to support Products A and B while Product C is a smaller secondary user.
A predetermined split could be:
Product A: 45%
Product B: 40%
Product C: 15%
The resulting allocation becomes:
Product | Fixed share | Allocated cost |
|---|---|---|
Product A | 45% | €5,400 |
Product B | 40% | €4,800 |
Product C | 15% | €1,800 |
Fixed allocation is easy to forecast and explain.
However, it does not automatically respond when consumption or business conditions change.
For that reason, fixed rules should be reviewed periodically.
The same €12,000 produces five different answers
Compare the results:
Allocation method | Product A | Product B | Product C |
|---|---|---|---|
Equal | €4,000 | €4,000 | €4,000 |
Usage-based | €7,200 | €3,600 | €1,200 |
Revenue-based | €6,000 | €3,600 | €2,400 |
User-based | €6,000 | €3,600 | €2,400 |
Fixed | €5,400 | €4,800 | €1,800 |
Every row allocates exactly €12,000.
Every calculation is mathematically correct.
But they represent different economic assumptions.
This is why cost allocation cannot be solved by arithmetic alone.
The important question is:
Which rule best represents why the cost exists and who should be accountable for it?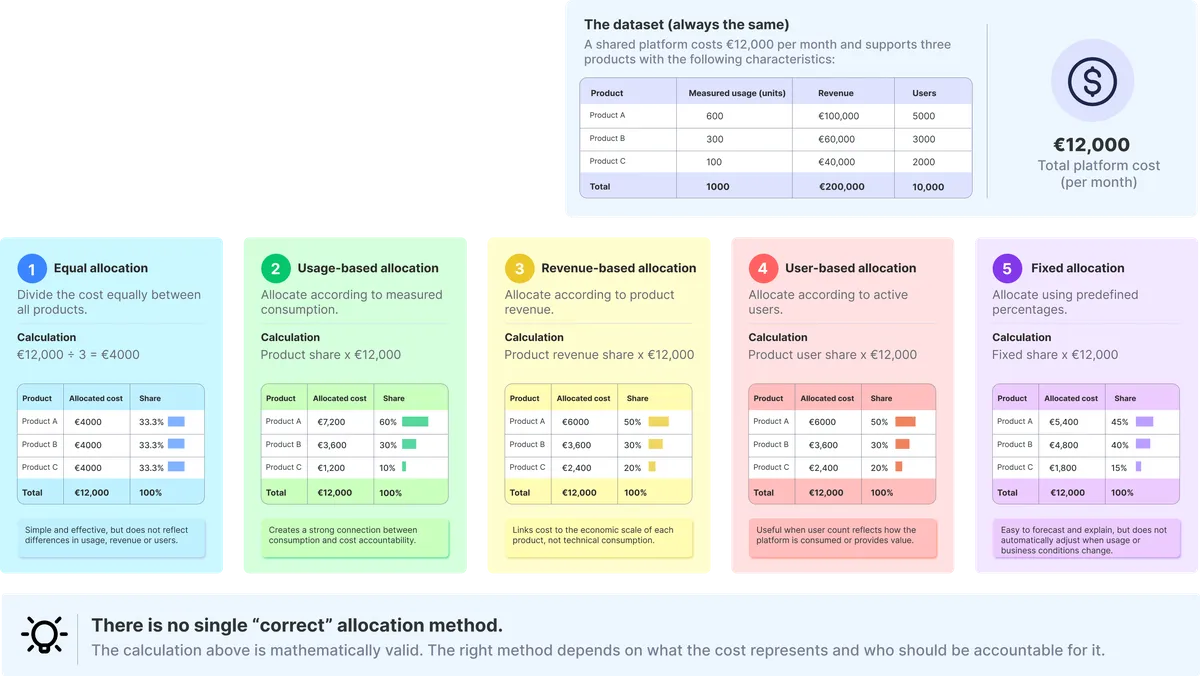
What about untagged cloud costs?
Tags and labels are commonly used to identify resource ownership.
For example:
team = payments
environment = production
product = checkout
But real environments rarely have perfect metadata.
Resources may be untagged, incorrectly tagged, use inconsistent naming conventions, or belong to shared services that cannot reasonably be attributed through a single tag.
Suppose a monthly cloud bill is €100,000.
Ownership can be established for €92,000.
The remaining €8,000 is unallocated.
A tempting solution is to distribute that €8,000 across the known teams so the report reaches 100% allocation.
That can make the dashboard look cleaner.
It can also make the data less truthful.
The case for an explicit unallocated line
Consider this example:
Cost owner | Cost |
|---|---|
Product A | €40,000 |
Product B | €30,000 |
Product C | €22,000 |
Unallocated | €8,000 |
Total | €100,000 |
The €8,000 unallocated line tells you something important.
There is cost in the environment for which ownership has not been established.
If you simply distribute it according to the existing allocation percentages, the accounting total still reaches €100,000, but the uncertainty disappears from view.
The organization can no longer distinguish between costs genuinely owned by Product A and costs assigned to Product A because somebody needed somewhere to put them.
An explicit unallocated category preserves that information.
It can also become an operational metric.
If unallocated spend falls from 12% to 4% over six months, the organization has measurable evidence that its allocation coverage is improving.
Allocation coverage is not allocation quality
Achieving 100% allocation does not necessarily mean the model is good.
A company could assign every unknown resource to a generic cost center and report 100% coverage.
Technically, nothing is unallocated.
Economically, little has improved.
A useful allocation model should therefore consider both:
Coverage: How much of total spend has been assigned?
Quality: How defensible is the relationship between the assigned cost and its owner?
This distinction matters because FinOps teams can otherwise optimize for a visually attractive metric rather than a meaningful cost model.
Shared costs should follow a defensible driver
Shared costs are unavoidable.
The question is not whether they exist but how they should be treated.
A useful starting principle is:
Allocate a shared cost according to the factor that most reasonably explains why that cost exists.
For compute, that might be CPU or memory consumption.
For storage, it might be GB-months.
For a support function, it might be customer count or service consumption.
For a shared platform, it might require several drivers.
Some costs may not have a sufficiently defensible driver. In that case, keeping them centrally funded or explicitly unallocated can be preferable to manufacturing precision.
Cost allocation vs showback and chargeback
Allocation determines where a cost belongs.
Showback determines who sees it.
Chargeback determines who financially pays it.
These concepts are related but not interchangeable.
You can allocate costs without charging anyone.
For example, a platform team might allocate €7,200 of shared infrastructure to Product A and display that amount in a monthly report. That is showback.
If the same €7,200 is transferred to Product A's budget or billed to a customer, it becomes chargeback.
For a detailed explanation, see Chargeback vs showback.
Cost allocation and unit economics
Allocation is also an important input into unit economics.
Suppose Product A generates 100,000 transactions per month.
Its directly attributable infrastructure costs are €20,000.
Its allocated share of common platform costs is another €7,200.
The relevant cost base becomes:
€20,000 + €7,200 = €27,200
Cost per transaction:
€27,200 ÷ 100,000 = €0.272
Without allocating shared costs, the reported unit cost would be only:
€20,000 ÷ 100,000 = €0.20
Both calculations may be useful, but they measure different things.
Understanding which costs are included in the numerator is therefore essential whenever unit costs are compared.
Cost allocation across hybrid and multi-cloud environments
Allocation becomes more difficult when technology costs originate from multiple systems.
A service might use:
AWS compute
Azure data services
an on-premises Kubernetes cluster
VMware infrastructure
SaaS applications
shared storage
observability tools
internal platform services
The business does not necessarily care which billing system produced each line item.
It may want to know:
What did Product A cost?
Answering that question requires costs from different sources to be normalized, enriched with common ownership information, and allocated using consistent business rules.
This is why cost allocation increasingly extends beyond cloud billing data alone.
How Exivity supports cost allocation
Once an organization has decided which allocation rules represent its business, those rules need to be applied consistently across the underlying data.
Exivity brings together cost and consumption information from public cloud, private cloud, virtualization, containers, SaaS, infrastructure, and custom data sources.
That data can be enriched with business context such as customers, departments, services, projects, and contracts before rates and allocation rules are applied.
This enables organizations to build cost models across heterogeneous environments rather than treating every technology provider as a separate financial silo.
The resulting allocated costs can then support reporting, showback, chargeback, billing, and unit economics.
The allocation methodology remains a business decision.
The role of the platform is to make that decision transparent, repeatable, and scalable across the available data.
Related: Chargeback vs showback · Unit economics · AI token economics · FOCUS, explained
Frequently asked questions
The questions people ask about this once they start doing it, in the words they use.
Ask us about your use caseWhat is cloud cost allocation?
Cloud cost allocation is the process of assigning cloud costs to the teams, products, customers, projects, applications, or other business entities responsible for consuming or benefiting from them.
What is shared cost allocation?
Shared cost allocation distributes the cost of a resource or service used by multiple consumers. The allocation can be based on measured usage, predefined percentages, business metrics, equal distribution, or another defensible driver.
What is the difference between cost allocation and chargeback?
Allocation determines where a cost belongs. Chargeback uses allocated costs to create a financial charge against the responsible team, department, customer, or other entity.
What are unallocated cloud costs?
Unallocated cloud costs are costs that have not been assigned to a specific owner. They may result from missing tags, incomplete ownership information, shared infrastructure, or deliberate decisions to keep certain costs centrally funded.
Should all cloud costs be allocated?
Not necessarily. Forcing costs onto consumers without a defensible allocation rule can create misleading financial information. Explicitly identifying some spend as unallocated can provide greater transparency.
What should we do with costs we cannot allocate?
Keep them visible as an explicit unallocated line rather than spreading them across consumers arbitrarily. Unallocated cost usually points at missing ownership data, shared infrastructure, strategic capacity, or incomplete metadata, and showing it as its own line makes those gaps measurable and easier to fix.
Can costs be allocated without tags?
Yes. Tags are one source of ownership information, but allocation can also use accounts, subscriptions, projects, consumption metrics, CMDB data, organizational structures, customer information, or custom business rules.
What is allocation coverage?
Allocation coverage measures how much of total spend has been assigned to an owner. High coverage does not automatically mean high allocation quality; the underlying allocation rules must also be defensible.
Which cost allocation method should we use?
It depends on the cost, the data you have, and what the allocation is for. Use direct allocation when the owner is known. Use usage-based allocation when consumption is measured. For shared costs without a usable consumption measure, choose between proportional, fixed, or equal allocation and document the rule, because the method changes the result even though the total cost does not.
How do you allocate shared platform costs?
If the platform meters consumption per consumer, allocate on usage. If it does not, pick a proportional driver that tracks real consumption as closely as possible, such as workloads, seats, or another measured quantity, and apply it consistently. The rule should be agreed with the teams paying for it and kept stable from one period to the next so results stay comparable.
Does cost allocation only apply to public cloud?
No. The same model applies to private cloud, on-premises infrastructure, SaaS, and other technology services. The difference is that public cloud arrives with a bill, while private and on-premises capacity first needs a cost per unit before it can be allocated.
How does cost allocation relate to FinOps?
Cost allocation is what connects technology consumption with business ownership. Showback, chargeback, budgeting, forecasting, and unit economics all depend on costs being attributed to the right owner first.
Want the specifics on your own numbers?
A demo scoped to the problem this guide describes, run by an engineer. Bring one cost source; leave with a recommendation.